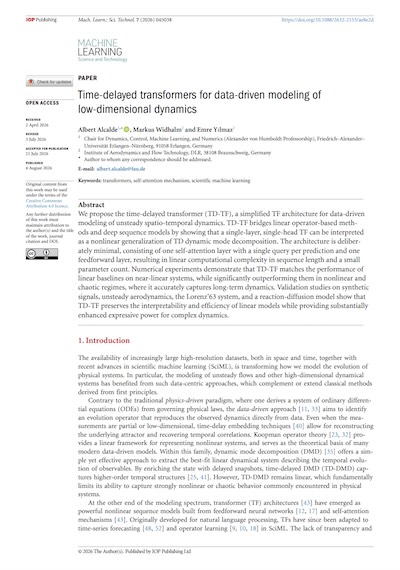
Today's article comes from the journal of Machine Learning: Science and Technology. The authors are Alcalde et al., from the University of Erlangen-Nuremberg, in Germany. In this paper they propose a model that combines the time-delay structure of TD-DMD with the nonlinear expressive power of a stripped-down transformer.
A few days before Thanksgiving 2008, Peter Schmid and Joern Sesterhenn presented a paper to the American Physical Society's 61st Annual Meeting of the APS Division of Fluid Dynamics. And in that paper, they invented what we now know as "DMD": Dynamic Mode Decomposition. A dimensionality-reduction technique that lets a researcher distill a complex dynamics problem down to just its essence:
Pretty simple, pretty elegant, and for a lot of problems in fluid mechanics and engineering: more than good enough. When you're trying to predict how airflow over a wing will evolve or identify the dominant motions in a fluid flow, for example, DMD can help you reduce a huge collection of measurements to the most important components, then estimate how those components will evolve forward. If you're trying to analyze vibrations in a mechanical structure, DMD can help you identify the dominant oscillatory modes and estimate how those vibrations will change over time. And as a result, DMD is now used by everyone from aerospace engineers to mechanical engineers to fluid dynamicists to applied mathematicians. Because it gives you quick results that are somewhere near the truth, and are good enough to use for forecasting, control design, model reduction, or downstream analysis.
Unless, that is, you're dealing with a system that isn't fully described by the variables you can measure at a single instant. You see, for many systems, it isn't enough to know the exact current state of the system. You need to know several states before that. For example: in order to know how quickly a car is going to come to a stop, it's not enough to know where that car is right now. You need to know where it was a moment ago, and the moment before that, and the moment before that. With that trajectory of temporal points you're then able to map out how fast it was going, how much it's decelerating now, and how much further it will travel (in what amount of time) before it comes to a rest. Without those previous frames, however, there'd be no way for you to calculate that.
And for those kinds of problems, there is now an offshoot of DMD called TD-DMD: time-delayed dynamic mode decomposition. In TD-DMD you don't represent the system using only its latest observed state, you build an enlarged state from a window of several consecutive previous observations. You then learn a (still linear) rule that takes that entire window of recent history and predicts what should come next. Once a new state has been predicted, the window shifts forward, the oldest observation drops out, and the newly predicted one becomes part of the history used for the next prediction. That means TD-DMD can represent much richer temporal behavior than ordinary DMD while still retaining a lot of the simplicity.
But, as with normal DMD, TD-DMD is only suitable to characterize systems that are inherently linear. What if yours is not? What if it's strongly nonlinear, with interactions that change depending on the current state. What if it's turbulent or chaotic? What then? How can you use either one of these systems if there simply is no linear approximation that is capable of accurately capturing the state-changes the system is undergoing?
Well that's where today's paper comes in. In it, the authors are building a tool that is intended to be used in just those kinds of situations. A model that combines the time-delay structure of TD-DMD with the nonlinear expressive power of a stripped-down transformer. The result, they argue, is a system that is capable of:
And since the architecture is deliberately constrained, it can do that without taking on all of the computational expense and opacity of a conventional transformer. On today's episode we'll walk through how this system works and how they evaluated it. Let's dive in.
The authors call their model the TD-TF: the Time-Delayed Transformer. But despite its name, it's not just a normal transformer that has been pointed at time-series data. The architecture has been deliberately simplified so that it resembles TD-DMD as closely as possible. The input is still a finite sequence of recent states, just as it would be in TD-DMD. But before those states are processed, each one is given explicit information about where it occurs within that sequence by attaching a normalized time coordinate to it. Each augmented state then passes through the same small feedforward neural network. And since that network contains a nonlinear activation, it can transform those raw measurements into nonlinear features before different points in the history are combined.
Those transformed states then enter the attention mechanism. Now remember, in TD-DMD each position in the history contributes according to a fixed linear transformation learned from the training data. So once that model has been fitted, the way a particular delay contributes does not adapt to the specific sequence currently being processed. But in TD-TF, things are different. This system uses the most recent transformed state as a query, and compares it with every transformed state in the preceding window. Those comparisons are then converted into attention weights representing how relevant each point in the recent-history is to the prediction being made right now. The transformed states are then passed through a learned value transformation and combined according to those weights. In this way, the prediction is no longer just a fixed linear combination of past observations. Both the representation of each past state and the amount of influence assigned to that state can depend nonlinearly on the data in the current sequence. The attention mechanism effectively replaces TD-DMD's static treatment of the delay window with a state-dependent one.
But the authors also make an important simplification to attention itself. Whereas a conventional self-attention layer allows every position in a sequence to interact with every other position, TD-TF does not. Its only job, remember, is to take a window of history and produce one prediction for what happens next. So rather than calculate every possible pairwise interaction in the sequence, it needs to calculate attention only from the final input state back across the history. Why bother with that tweak? Because making that modification changes the computational cost of attention from growing quadratically with the length of the history to growing linearly with it. And the rest of the architecture is similarly minimal: there is only one transformer block, only one attention head, the feedforward stage comes before attention, and the normalization layers are omitted. The many residual connections found inside conventional transformers are also replaced by a single model-level residual connection. And that final residual structure means that the network is trained to predict how much the state changes from the latest observation, rather than having to reproduce the entire next state from scratch. At inference time, that predicted change is added to the latest state, the resulting state is inserted into the history, and the process repeats recursively to generate an entire future trajectory.
Unlike TD-DMD, whose parameter count grows as more delays are added, TD-TF can look farther into the past without requiring a new set of trainable parameters for every additional time step. The computation does increase because the latest state has more previous states to examine, but the model itself does not grow with the history length. And the architecture preserves a recognizable connection between the input history and the eventual prediction: you can inspect the attention weights and see which delayed states the model treated as most relevant on a particular prediction. That doesn't make the network completely transparent, since the feedforward transformations themselves are still learned nonlinear functions, but it does preserve considerably more structure than a deep general-purpose transformer.
The question is: does it actually work? To find out, the authors tested the pipeline on four different systems of increasing complexity and compared it against both TD-DMD and a nonlinear neural-network baseline that used the same delayed history but did not have attention.
Taken together, the experiments suggest that attention is doing something useful here. But they also suggest that TD-TF's advantage appears primarily when the delayed evolution itself is genuinely nonlinear.
So what does this all mean? What can we take away from this? Well not that TD-TF makes DMD obsolete. In fact, the paper demonstrates almost the opposite. When a simple linear model accurately describes the dynamics, it can still be the better tool for the job. I think the takeaway, instead, is that we don't necessarily have to choose between classical mathematical models and enormous neural networks. Sometimes the most useful path is to identify exactly where the classical model breaks, introduce ML specifically at that point, and preserve as much of the original mathematical structure as possible. Want to go deeper? Make sure you download the paper.